Thursday, February 23, 2006

Link Me Or Else!

Here we go again with a persistent raging linkaholic badgering the shit out of me to link to his crappy little directory website so he can get a few AdSense clicks.

Hi YouBigWebStudYou,

I sent you a link request for bullshit-directory.com to see
if you would be interested in exchanging links.

I realize you are probably but wanted to let you know that I will be
removing your link next Wednesday if I don't hear back from you.

You can verify your link is by going to:
http://realfuckingannoying.com

with the following details
Title- Link To Me Please
URL-www.imbeggingyou.com
Description-I'm the biggest pain in the ass link-to-my-site whining spammer you've ever seen so link to me now before I beg and plead more.

If you do add my site please use the below information and let me know
the location you added it so I don't remove the link to yours
unknowingly.

I hope to hear from you before 2nd March 2006 but if not then I'm bound
to remove the link from my site.
Well fucking remove me already and stop sending me this shit!

Didn't the dead silence after your first spam give you a fucking clue?

If I could get my hands on you they'd have a new opening homicide scene for CSI next week so just keep it up, your luck is about to run out.

Oh yeah, it's a good thing you're in India so CAN-SPAM can't be used against you and you aren't registered with GoDaddy so they can't blackmail you to get your domain back. However, if there is a god one of those nasty little bugs in your water will give you atomic diahrea and you'll shit out a vital organ and die.

Wednesday, February 22, 2006

Search Engines Let Scrapers Bypass Spider Traps!

Just when you thought you've seen it all the actual search engines themselves can be used by scrapers to bypass spider traps. How this is accomplished is the scrapers find all of the indexed page names from your site in Google or Yahoo and then download pages the using known page names from your site thus side-stepping spider traps as they aren't actually spidering your site at all.

Therefore, just eliminating your pages from being CACHED in the search engines doesn't stop scrapers from still using the remaining data to their advantage.

Some days it just doesn't pay to get out of bed.

Tuesday, February 21, 2006

Another Plug-n-Scrape Component

Yet another toolkit letting armchair programmers attempt to grab my web pages.

Yawn.

This one ID's itself as:

IP*Works! V5 HTTP/S Component - by /n software - www.nsoftware.com
And their web site claims:
The HTTP component can be used to retrieve documents from the World Wide Web.
Might want to revise that to "used to be able to retrieve documents" as it went splat against my brick wall but I found it's calling card in my auto-blocked bot log.

Chitty Content

Must be the new wave of affiliate bots as I also got hit today by the Chitika ContentHit crawler or whatever the heck it is.

No way to verify this bot as reverse DNS for this IP address just claimed to be from Charter Communications.

71.10.233.52 Chitika ContentHit 1.0
This new bot of the day chit's just getting old.

Cell Phones and PDAs Can Piss Off

All these damn cell phones and PDAs all have unique user agent strings and for the last few months the handful that hit my website are all being told to piss off.

You people making cell phones and PDAs better wake up and smell the coffee as I'll be damned if I whitelist a bazillion user agents just to let your pissy products see 5 lines of my web site.

You all better come up with some better ideas for cell phone user agents as this unique name per phone shit isn't gonna fly.

CJ Quality Bot

Well here's a new one that I've never seen before from our friends at Commission Junction.

216.34.209.23 CJNetworkQuality; http://www.cj.com/networkquality
Unforunately they bounced off the walls, think I should let them in?

They might delist my site if I don't but based on the revenues I earned with them last month it's kind of a why bother IMO.

Fine, time to whitelist CJ, sigh.

Saturday, February 18, 2006

Robots.txt gives Bad Bots clues to access

In a rather lengthy debate with the owner of Majectic-12 on WebmasterWorld the issue of robots.txt came up over and over and I finally revealed that robots.txt is arcane and a real problem in the world of scrapers as it gives them clues to accessing your content.

Not only does robots.txt reveal which user agents may be blocked in the .htaccess file but it also reveals which agents are allowed into your server. Any roque bot not getting access to your site can simply examine the robots.txt file and use any allowed user agent name to get past the barracades.

My recommendation is to use a generic robots.txt file such as follows:

User-agent: *
Disallow: /stayout.html
Disallow: /keepaway.html
Disallow: /cgi-bin/
Disallow: /someotherdirectory/

Then allow and disallow robots privately in your .htaccess file only to keep that information away from prying eyes and give the lamest of the scrapers fewer clues how to penetrate your site's defences.


UPDATE: the Majectic-12 conversation at WMW is on hold pending review now so maybe I spilled to many beans on site security issues. It was a great debate, hope it comes back only slightly altered.

Cornucopia of Random User Agent Strings

When my bot buster first started operating I noticed a few gibberish user agent strings now and then as I'm sure the theory behind this is if a website is blocking known user agents then you can skirt past that technique with a string of gibberish.

The problem is that they've noticed nothing is getting thru and random user agent string usage against my site is escalating to the point it's hysterical to witness them thrashing.

Small sampling of thousands the other day:

66.148.68.37 2uigq2oecesvv2nwso rwiakBsBue Bobgw2nuB
202.125.44.200 efeSthqvkr11ticgo1iovjjrdwakbbd
66.148.68.34 emwx4cxnd pedafhfpac
66.148.68.34 ymdexin7xpebtulwnxew
202.125.44.199 pepgfu wjdjqrxckulhwiflmrdsmkc mjvldn
84.180.94.183 mairwthe Ifirpl8tiwotwyi lsu
84.180.94.183 r9Hreiynmkxmpjh ioHmmknpdmid
66.148.68.34 ewoqaohlcegoD emkdywx
66.148.68.34 obtDrqhxogxsewDfcDktb
209.190.21.100 bedmdFjkFhc4a noFjajakffieapvngdtpwxk
209.190.21.100 gdouk6Ss6nnykg66hvojc6txjsecuu
209.190.21.100 aphErvbtijj vulgctlslo
209.190.21.100 jgbhwntsdlprxcwogijI8orrw b8
209.190.21.101 DrbspcgyubxrpeikfiihxD mh
209.190.21.101 jvAhnviAjwwud8gymvewtcqhehgbAcytyqdxq
209.190.21.101 cvwkvl6kfujhqlujqblFl dffrepmrxdspmdFjq
209.190.21.101 obmJJkjtslbqreh6pwx6epruhptrpJbk
This is why I keep preaching that blocking by user agent only works for the legit crawlers that want to allow you to block them but the scrapers aren't playing by any of the old rules and I'm shocked these idiots just didn't use a browser string which has a better chance at least getting a handfull of pages of my web site until they get too greedy.

Sorry webmasters but the rules have changed in how this game is being played and you really need to block all non-browser agents and allow legit crawlers like Google, Yahoo and MSN by IP only. Any other method is just wasting your time as random user agents cannot be stopped by your old traditional techniques.

The blacklist is out, the whitelist is in.

Wednesday, February 15, 2006

Fuckers For Sale!

Found this little gem while playing around with AdSense testing relevant ads on dynamic search pages by using a GET vs a POST and just for shits and giggles added "?q=fuckers" to the end of the URL.

Well, much to my surprise one of the ads was extremely relevant and not only that, it appears you can compare places that sell fuckers on shopping.com and get a fucker of your choice for the best price!

I don't make this shit up, see it for yourself:


So much for family friendly AdSense ads!

Tuesday, February 14, 2006

Some days it seems so obvious

Today I was looking in the search engines for more signs of scrapers showing up in the SEs with my error messages and found a few more of these idiots. Then it crossed my mind that it would sure be nice to know which IP addresses that got blocked from scraping were assoicated with which web sites.

Well duh.

It's obvious I need to embed a bug in my text that ties the scraper to his web site so today starts the next wave of linking the abusers to their websites and opens up opportunities for automatic abuse reports that tie them all together.

Now this has me giddy, I can hardly wait!

Crawl Delayed RSS

Sometimes interesting solutions to problems just present themselves out of the blue as a discussion about Aaron Pratt's SEOBUZZBOX being supplemental results instead of the authoritative source gave me an idea.

What if you simply delayed updating your RSS feed until Google, Yahoo, etc. had already crawled your new content pages?

Theoretically this would improve your chances of being the first place that the new content was discovered and the news aggregators would then all become secondary sources for your information.

Would Google still make SEOBUZZBOX a supplemental result because of it's lower page rank or would fresh original content float to the top based on a first come first served basis and make the aggregator take the hit on duplicate content?

This is an experiment well worth trying, Aaron, you listening?

Anyone got any guesses what would happen?

Carnival of Scraper Sites

These circular scraper sites must be the worst sites I've encountered so far as all the scraped content is linked internally and no matter what you click on you just keep going round and round inside the scrapers web site until you click on an advertisement to escape.

These come in a couple of flavors such as the Moron Loop-de-Loop, the Loser Landing Strip and the Doorway Pages to Hell.

The Moron Loop-de-Loop sites contains snippets of your site and something that looks like it's a link to your web site but instead it links deeper into itself showing yet another page that is more thematic based on what you clicked. You can click and click and go round and round in this site because the only exits are AdSense exits. This is actually quite ingenious as you get more specific ads related to your area of interest if you keep clicking on more thematic links that seem to narrow your focus of interest but never provide anything interesting, except the ads.

The Loser Landing Strip is an interesting cloaking variation as this supposedly single page web site appears to have an infinite amount of cloaked pages behind it but only Google's IP addresses see that cloaked content, you only seel the silly landing page. No matter what snippet of page content you see in the search engine, no matter what nav links you click on in the web site, it's always that same landing page. All paths lead round and round to the same page so just click the ads already and give them what they want!

Door Way Pages to Hell is an interesting variant as it is part Moron Loop-de-Loop and Loser Landing Strip in that the first site you hit looks like a blog with links to actual web sites but the blog is actually the starting point on a trip to hell. Each link in the blog that says it's taking you to a useful web site actually has a link to one of their other scraped content sites instead, which of course link to yet other scraped content sites. It's a freaking AdSense pyramid scheme disquised like a domain park, it's absolutely frightening that someone would build such a large network just to keep a surfer going in circles until they catch a click.

Definitely a new low in scraping as the original content owner gets no value, not even a link, nothing but being used to get keywords and phrases to divert people to their sites.

Not sure it can get much worse than this but I've been wrong before!

Monday, February 13, 2006

Bullshit Gourmet

Sometimes when the little frozen food meals are on sale at the store I'll snap them up to get the 10 for $20 sale price and have a nice quick microwave lunch every now and then. Well, this weekend the fridge was bare and the usual brands weren't on sale at the market so what-the-hell let's see what these Budget Gourmet's are like since they're on sale.

Today is the moment of truth.

Opened one of these little boxes up and it has all the food, what little there is, on one side and all the sauce on the other.

Wait a fucking minute, half of this itty bitty box is reserved for a thin layer of sauce?

You must be fucking joking.

Completely unsatisfied ripped open yet another box.

Same bullshit, small pile of crap on one side, sauce on the other side.

BULLSHIT!

FUCKING BULLSHIT!

I'M STILL HUNGRY AND I'VE JUST BEEN FUCKED IN THE ASS BY A FUCKING FROZEN FOOD COMPANY AND NOW I'M FUCKING PISSED!

McDonald's anyone?

Sunday, February 12, 2006

Cloaking Scrapers Busted

Yesterday was a sad day for one Russian scraper that just had a large number of websites busted for cloaking in Google and they were just reported to Yahoo today as well.

How they were busted is simple, they scraped my site!

Since my scraper stopper was deployed it's been giving all the scrapers a very unique message which they were happily scraping and including with their additional scraped web content. Wait a few weeks for the search engines to continue to crawl and update and VOILA! this message starts to appear on web sites. Clicking on the website in question and the message didn't appear but clicking on the CACHE copy of the page in Google and there it is, cloaked in all it's glory.

Report these sites and POOF! they are gone.

It's like shooting fish in a barrel and more fun than allowed by law.

Come on you cloaking scrapers, take my pages, I dare you...

Saturday, February 11, 2006

Scrape Me Up Scotty

Finally I've had an out-of-this-world scraping experience when someone tried to offload about 500 pages via a satellite. Thanks to the fine people over at DirecPC for hosting this little bandit my scraper stopping efforts have now entered the realm of aerospace.

I can see the headlines now:
Earthly Bot Stopper Blocks E.T. Scrapers

It's safe to hazard a guess Ray Bradbury never, in his wildest imagination, thought people would use satellites to steal websites.

Friday, February 10, 2006

Scraper Sites are GOOD?

Usually I have a good deal of respect for Martinibuster as he's a cool dude and has some good insights into a lot of SEO and webmastering topics. However, when I read his article "Scraper Sites are Good for You - Surrender Your Content" my first thought was to print it on toilet paper so I could give it the proper respect it deserved.

Come on Martini, you can't be serious about letting people waste your bandwidth, steal your content, and spam the SERPs with your own junk just to give you links?

Martini claims "Scrapers: There is Nothing You Can do About it" which is totally wrong! I'm stopping those bots, AlexK's script snares them and BotBuster and Bandwidth Protector claim they will also stop them. Can't comment or endorse the latter products as I've never used them but they do exist as well as some others so webmasters not stopping scrapers just means they're lazy or cheap at this point.

Then Martini makes me spit soda across my keyboard with "Surrender to the Scrapers... It is Better for You". What a load of crap my friend. Just ask Aaron Pratt of SEOBUZZBOX how good surrendering to the scraper is as he's being lumped into supplemental results as the scrapers aggregators are being indexed first and Google thinks Aaron is the duplicate content which is just wrong.

So Martini says "scrapers do more good to you than harm" which gets the bullet list:

  • Scrapers can put your content in supplemental results
  • Scrapers can rank above you in the SERPs and get the first shot at AdSense and affiliate income using your content
  • High speed scrapes of 100s pages/second are like DDOS attacks and knock servers offline until they stop scraping keeping visitors from clicking your ads
  • When servers can't respond due to scrape attacks Google, Yahoo and MSN get time outs on pages and SERPs drop
  • Rampant scraping can run up your bandwidth charges and you pay for their excess
Nope, no harm no foul, nothing wrong with scraping.

What I can state with certaintly is that since I've started blocking scrapers my SERPs and REVENUE are both up substantially and that's about the only major change I've made to my site recently.

Try reading one of Martini's other articles that made sense instead, he's really a nice guy, just slightly misguided on the topic of scrapers is all.

P.S. Doesn't scraper and bot stopping sound like a great session topic for PubCon Vegas this year?

Thursday, February 09, 2006

Referer Spammer Revenge!

Today I caught some referer spammer bombarding my web server by hitting the same page over and over and over with only the referer changing.

To put it mildy, this pissed me off.

When I started looking up each domain I noticed something fascinating in that they all had the same AdSense account and were all registered at GoDaddy.

Recent topics on ThreadWatch about GoDaddy locking abusers domains provided a true inspiration today. Instead of wasting my time putting this asshole in my banned list of IPs and domains to keep him out as would be my normal routine, I reported him to both AdSense and GoDaddy abuse and will be waiting and watching to see if either of them take action.

If GoDaddy shuts his entire array of websites down this will be the best defensive action to take against referer spamming yet, I'll post the results if any when I see the domains go offline.

BTW, I also added referer spamming detection to my bot blocker today so I'll be snagging more of these idiots on a regular basis if this is a huge problem. I'm considering making the bot blocker automatically perform a whois on the domains when this is detected and send automatic abuse letters to the proper parties.

This could be fun ;)

Wednesday, February 08, 2006

Polish Robot You Can't Pronounce

Only a polish robot would be looking for polish websites on my server in Texas - sigh.

Anyway, we found Szukacz trying to snoop around but alas, it slammed into the great wall protecting my site.

Looks like it supports robots.txt according to the web page but who knows.

Burf Barf Puke

Someone in jolly old England unleashed Norbert the Spider upon my site which appears to be sent on behalf of the fine people at Burf that claim "BURF - Alternative Search Engine and Entertainment Portal"

Alternative to what, finding what I'm actually looking for?

Then I dediced to click on the "Your Ad Here" link just to see what one gets for the money to advertise with Burf and it's placement on a truckload of search sites I've never even heard about.

Well, it's cheap advertising but then again my URL would probably get about as much exposure putting it on the bottom of my shoe.

Yacy my Assy

Filed under "Who Needs Another Crappy Search Engine" we find something called Yacy that claims to be a P2P distributed search engine whatever the fuck that means. I'm translating that back into English as a free-for-all scrapefest bandwidth waster.

They claim it's "Easy to install!"

I claim it's "Easy to block!"

Toodles.

Monday, February 06, 2006

Anti-Social Bookmarking

Well here comes the new leech-of-the-week Susie came crawling and went head first into an error page. Sych2It claims that "Dead and out of date links are automatically reported" but I'm not sure how they would know for sure as they got a slap in the face instead of a web page.

Fine German Engineering? HA!

The AnonyMouse proxy slammed head first into my bot blocker.

Come on people, if you're gonna waste your fucking time writing an anonymous proxy server the least you can do is attempt to fake being a browser instead of making your user agent string your domain name.

Give me a goddamn break.

Friday, February 03, 2006

Big Decisions Time for Bot Blocker

Getting real serious about converting the bot blocker prototype into a product and all the agony that goes along with developing, launching and supporting a new product brings back fond nightmares, um, memories of products launched in the past.

Trying to determine if I should write it myself or hire someone to write it to speed it along, look for equity partners from the beginning, whether to even sell it as a product, open source it, or whatever the hell to do with it and the whole process is just maddening.

Talking to a few people the last few days, we'll see how it goes.

I knew there was a reason I've been claiming to be retired the last few years!

SuperBot Found My Kryptonite

Sorry you're not so SuperBot after all as you couldn't even leap over my index page without tripping and falling.

The author claims:

Unlike other offline browsing tools, SuperBot is fast AND powerful AND and easy to use...
Whoops!

Should now read "Just like all offline browsing tools it was stopped dead in it's tracks when it hit IncrediBILL's Bot Blocker"

Better hope your customer that tried to download my website doesn't come looking for a refund!

EUREKA! Proxy Detection Thanks to Idiots

Thanks to some sloppy work by some rank amateurs running proxy servers they pointed out a flaw that many anonymous proxy servers share that are now allowing me to automatically detect proxy usage and block the damn things in real-time.

Of course this doesn't work on all proxy servers but it caught 10 of them just today.

I should've spotted this happening weeks ago but at the time I came up with a different hypothesis for the data that presented itself which today, with additional clues, makes it obvious many of these hits are via proxy servers.

Wow, it's amazing how such simple revelations can rock your world so easily.

This is cool - blog ya later as I need to work on proxy busting now ;)

Scientific Search Halted

Here's another crawler that lost it's way called Scirus that claims to be a scientific search engine yet was trying to roam around my non-scientific web site. They claim to be powered by Fast but they were stopped dead in their tracks by my bot blocker that said not-so-Fast, heh.

Sorry boys, you need to find a new lab rat to play with.

Rufus is a Dufus

When it just couldn't get any sillier along comes something claiming to be RufusBot which claims to be a good little bot but others claim it's personal scrapeware.

I don't care either way as it's not scraping here and don't let the door hit you on the ass on your way out Rufus.

Proxy Mouse Ate the Poison Cheese

Too funny, my spider trap killed a mouse, ProxyMouse as a matter of fact.

These leeches are just like the other proxy service that strips all of my ads off the page by default and slaps their own Yahoo ads on the top of the page but NOT ANYMORE!

What's best is how I caught them thanks to MSN which somehow attempted to crawl my site thru their proxy. When MSN was crawling their proxy server just passed whatever user agent string, in thie case msnbot, thru to my server. Suddenly my server sees msnbot on an IP address that doesn't belong to Microsoft and SNAP! they are busted.

No more Yahoo income for you off my back, your filtering asses are done.

Buh bye, see ya, wouldn't want to be ya!

Thursday, February 02, 2006

Yahoo Blogs Doing a Content Crawl

Not sure what good old Yahoo is up to exactly as this spider hasn't shown up in my spider trap before but Yahoo Blogs is attempting to crawl the content from my RSS Feeds directly. Not sure if they intend to display the content directly to the user or still redirect to my site so I'm not sure I'm letting them step past the RSS feed just yet.

209.191.83.13 Yahoo-Blogs/v3.9 (compatible; Mozilla 4.0; MSIE 5.5; http://help.yahoo.com/help/us/ysearch/crawling/crawling-02.html )

Official Name: crc4.opn.search.mud.yahoo.com
IP address: 209.191.83.13

Maybe it's harmless and I'll let it pass, something to contemplate over a beer.

Why is WaveFire crawling?

Some Canadian consulting company called WaveFire has a bot trying to crawl for reasons not divulged on their website. Would've been nice if they posted something about what purpose they had in attempting to crawl sites.

64.141.15.109 Wavefire/0.8-dev (Wavefire; http://www.wavefire.com; info@wavefire.com)

Official Name: search-d-02.internal.wavefire.ca
IP address: 64.141.15.109
Sorry, but your fire was put out and your spider was splattered.

Wednesday, February 01, 2006

Expanding Bot Blocker to More Sites

This week I'm going to install my bot blocker on 2 additional websites and see what level of abuse these sites are taking just to see what kind of an impact this technology could have on smaller less active web sites.

Don't get your tits in a twist just yet as it's still not converted to PHP and is still just a protoype no where near being a product for release.

On the more amusing side the message my site pops up when scrapers hit telling them they've been stopped has started showing up in the search engines as these automated scraping idiots haven't realized they're showing the world just how stupid they are.

What's more telling is which search engines show which sites with these messages vs. others that don't as I'm getting some insights into what some search engines are blocking as spam sites.

Blasphemers use IncrediBILL in VAIN!

Someone is using my name in vain to describe someone else in some big embittered bullshit battle about some religious horseshit.

Just what I need, now a bunch of idiots [you know who you are] will think I'm that person.

Fucking lovely.

Bend Over When Upgrading WebCeo

Finally decided to upgrade to the latest WebCeo and it did pop up a message about "losing reports" in that all existing reports should be printed before upgrading etc.

OK, big whoop, didn't need the old reports, could care less.

What that little message DIDN'T SAY was you would lose all projects, all profiles, and all that stuff and didn't even bother trying to automatically upgrade the data from the previous version leaving me to think all I was going to lose was the ranking information in the reports.

The new WebCeo version is now installed and pops up completely blank.

FUCK!

WebCeo needs to make those warnings a little more specific:

  • You'll lose all reports
  • You'll lose all projects
  • You'll lose all profiles
  • You'll lose EVERY FUCKING THING
Not that this was a complete crisis as I maintained a list of all the keywords for the ranking reports in a set of separate text files as WebCeo doesn't [didn't] have any easy way of just exporting my keyword list so I maintained it externally which worked out in the end as I just cut and paste the whole list of keywords back into the projects as I recreated them.

Back in business but the next time they release a major upgrade I may be tempted to try a different product instead as this was not amusing.

Excrutiating Back Pain

Pulled a muscle the other day which resulted in the brief hiatus from the blog as sitting in my desk chair long enough to write a rant was just too painful and I was in too much pain to use the laptop even as looking down pulled the muscle and hurt so I caught up on television watching instead.

BTW, when I'm in pain the level of cursing escalates to a new plateau so the blog may become TV-MA rated over the next few days until my back gets better as I need to release all this pent up hostility somewhere.

You've been warned so brace for impact.

The Ultimate Online Pharmaceutical

This is the topic of a bazillion spams every week which begs the question of which one of you limp dick assholes out there buy pecker pills via these mail order bullshit spams?

They wouldn't keep spamming me with this fucking garbage if one of you limp mother fuckers weren't buying these goddamn pills so just step forward so I can cut your fucking dick off and end my suffering thru these spams as a bloody stump doesn't need viagra, it needs a bandage.

Just ask your doctor for the pills you impotent bastards and leave me the fuck out of this.

Cache Hysteria Pandemic

WARNING - STRONG LANGUAGE ABOUT FUCKING MORONS

Everyone has lost their fucking mind on this topic and the fact that Yahoo and MSN have page cache doesn't matter as the only search engine being bashed over this topic is Google.

The world is not flat and the earth DOES NOT revolve around Google.

The non-stop "Google Google Google Google" mantra is getting old and you're all starting to sound like a bunch of fucking narrow minded cultists so get a life, get a clue, open your damn eyes and look around.

The best nonsense argument I keep hearing is that the less technically savvy authors out there shouldn't have to learn how to disable cache, it should be opt-out by default, blah blah blah wasting precious air spouting bullshit. OK, in an utopian world perhaps being cached would be opt-in but it isn't so just get past it and quit dwelling in fantasyland you delusional twits! Any author that can figure out how to get his content online and can set up meta tags for description and keywords can insert a fucking line to disable cache!

Holy fuck!

Have you all lost your fucking minds in that you would rather sit and whine for months and years about pages being cached instead of just inserting that one line into your template?

Got thousands of pages?

Maybe someone can get off their lazy ass and whip out a simple server side script that will update your entire httpdocs folder on the server inserting the no cache directive in all web pages.

How about fixing the tools used by the legions of technically dim-witted like Mambo/Joomla, WordPress, FrontPage, DreamWeaver, etc. and make cache opt-out the default in all your pages.

Or just drop that line in your template, all the templates should have it, you hear me template designers? Take those iPod ear buds out of your waxy ears and listen up - ADD IT TO YOUR FUCKING TEMPLATES!

Lazy whiny assed shitheads, you're really getting on my nerves.

Stop bitching and moaning and just FIX YOUR FUCKING SITES and the cache argument would go away on it's own in a few months and be a moot point.

Fucking lamos.

Monday, January 30, 2006

A Banner Exchange - How 90s

Well, I know what the competition was up to now as they just launched a banner exchange network.

Come on people!

Banner exchanges didn't work when they first came out as people with traffic didn't need them and people without traffic couldn't generates hits to bring in the traffic so it was always a waste of time.

Lame lame lame.

Should've saved that banner ad revenue and used it for beer.

Sunday, January 29, 2006

C T Scans from Hell

Have you ever had the joy of a CT Scan?

Had one this morning and it's a lovely experience when they strap your ass to a small plank and zip you back and forth thru a nuclear reactor, not to mention all the radioactive dye they inject into your veins to see certain stuff.

I'll bet if I jerked off in the bathroom with the lights off right now my sperm would glow in the dark.

Today was a tale of two arms.

The nitwits in charge couldn't seem to find a vein to inject the dye into today which was probably because I downed a bunch of whiskey last night in my usual 'night-before-CT' anxiety drink-a-thon which dehydrates my dumb ass and thus makes the veins harder to spot.

Oh well, let them earn their pay to torture me.

Recently they just introduced paper underwear to put on during the scans so those of you that don't wear any crotch covers in the first place don't have your goodies waving in the wind for everyone in the room to see.

About 2 years ago I remember another CT Scan where the nurse yelled at me "close your legs, I don't need to see that" to which I replied "I'm wearing black briefs so all you're seeing is pink leg but if you really want I can whip it out for your viewing pleasure".

She shut the fuck up.

Bet she flunked anatomy and I'm sure she isn't getting laid when she can't tell thigh from ball.

Stupid stupid nurse, get your tubes tied, stop now before you pollute the gene pool.

Saturday, January 28, 2006

Get a Grip You Loon!

Where does someone come off going nuts on me about a free listing on a free website?

Someone sent about a dozen emails and left a bunch of voice mails ranging from 7am-11pm while I was away for a couple of days jumping up and down wanting instant support for something that cost them nothing.

Come on people, it's FUCKING FREE!

This is the same reason I started dumping customers opting just for my own websites to get away from whiny assed people so DON'T PUSH ME ASSHOLES or the plug could be pulled!

Spammers Succeed Elsewhere but WHY?

Went looking for other sites potentially hit with the same spam garbage that my site kicked out and was shocked at just how vulernerable all these sites were.

Come on people, these spammers were trying to submit their garbage via an HTTP GET instead of a POST command so it's obvious there are some real shitty programmers out there just letting any old crap get submitted any way it can. Guess I never realized just how bad blog spam is as most places I frequent are pretty clean. However, what I saw today after reviewing a bunch of sites hit by the idiots knocking on my door is that most of the blame can be placed on shitty programming and poor validation techniques.

Case in point is this article "Some Things I Learned in 18 Years of Programming" and apparently in all those years form validation and anti-spamming techniques weren't in the list. Scroll down the page and you'll see what I mean, a real belly laugh if it wasn't so sad in the first place.

More blame could be put on the spammers but it's like locks, doors and theives. If you don't lock your doors and they loot your house then you get what you deserve for being complacent. Remove easy access simply by locking the door or installing a security system and the lazy opportunists give up quickly. That only leaves you to contend with the more sophisticated spammers but unlike bandits putting guns to your head, spammers are a usually a little easier to stop especially the greedy ones, without taking a bullet to the head.

Oh well, not my problem with the exception that the idiots running wide open spamware encourage the little fuckers to attempt it on my site.

Friday, January 27, 2006

Attempted Submit Spammer Too Stupid to Spam

Today I was looking for something in a log file just to see what was up and stumbled onto some HUGE repeated strings attempted to be submitted over and over, always different data,

Someone appears to be hellbent to muck up my directory but they went overboard and didn't make sure the submission validated so my form submission pages bounced hundreds of them.

Lucky me!

What a mess that would've been!

Dropped the IP in the "DIE VIOLENT!" database so we don't have to worry about it for a few minutes.

Giving Scrapers a Cookie

Some scrapers appear to actually use the cookies your site transmits just to make sure they don't get stopped in case you block visitors that don't use cookies. In order to turn this to your advantage you can save the original IP address in the first cookie issued. This seems to be snaring a few of them as I'm using that IP in the cookie, if present, to track these idiots so that when they come back under different IPs, assuming they use some proxy or AOL with rotating IPs, that cookie they keep transmitting allows me to link their continuing activity to the original IP address.

So much for the IP shell game you morons.

Thursday, January 26, 2006

When Competitors Lose Their Minds

Sitting here minding my own business and this opt-in spam drops in my Inbox with a plea to buy advertising to generate some revenue for a new project for their web site.

Valley Girl sounds suddenly come out of my mouth:
"Like, Oh My God! Grody! Barf Me Out!"

Then the loud hyena laughter fills the air and dogs start barking blocks away.

Reading further they give the stats on exactly how many ads run maximum and that the placement costing a trivial sum of money is for a YEARLY rotation, not monthly but YEARLY.

Did some quick math and started yelling "YOU STUPID FUCKING MORONS!" as the amount being raised for this "project" is less than my AdSense pays in a few days while these numbnuts are horribly underselling the space and poisoning the well.

Hopefully my advertisers are smart enough to know that you get what you pay for and these wacky pleas for help show just what a weak player they really are.

Almost makes me want to call them and explain the facts of life but I'd hate to make them too smart if you know what I mean.

Idiots.

WebAbuse 2.0 Overnight Stats

Just to give some of you a hint that I'm not exaggerating about the amount of site crawling going on here's a list of 122 different IPs and agents automatically blocked last night that collectively attempted to access many thousands of pages. Some seem to have specific targets and only go after a few pages every time they return but others want to deep crawl the crap out of my site.

When you add it all up the bots are sometimes accessing more pages than the actual site visitors because this list doesn't include authorized bots.

FYI, don't be fooled by what you see just because the user agent looks legit means nothing as a human can't click on and read 200 pages in 150 seconds. It's possible there is an innocent or two that was snared, but considering what's at stake I don't really care anymore.

This is the future, run for cover:

12.221.77.114 Mozilla/4.0 (compatible; MSIE 6.0; Windows NT 5.1; SV1; .NET CLR 1.1.4322)
128.2.220.167 PrivacyFinder/1.1
130.158.81.39 Wget/1.10.1
131.107.0.84 SandCrawler - Compatibility Testing
134.96.1.195 AnswerBus (http://www.answerbus.com/)
137.43.154.203 NutchCVS/0.06-dev (Nutch; http://www.nutch.org/docs/en/bot.html; nutch-agent@lists.sourceforge.net)
139.18.2.43 findlinks/1.1-a8 (+http://wortschatz.uni-leipzig.de/findlinks/)
142.167.88.250 internal zero-knowledge agent
144.131.251.29 Mozilla/4.0 (compatible; MSIE 6.0; Windows NT 5.1; SV1; .NET CLR 2.0.50727)
151.24.66.200 Internet Explorer 5.5
162.40.193.253
172.169.142.20 Mozilla/4.0 (compatible; MSIE 6.0; Windows NT 5.1; SV1)
172.203.82.76 Mozilla/4.0 (compatible; MSIE 6.0; Windows NT 5.1)
193.165.250.22
193.42.229.3 NutchCVS/0.7.1 (Nutch; http://lucene.apache.org/nutch/bot.html; nutch-agent@lucene.apache.org)
193.47.80.43 Exabot/2.0
194.167.196.3 Wget/1.10.2 (Red Hat modified)
194.67.3.21 Mozilla/5.0 (X11; U; Linux i686; en-US; rv:1.7.12) Gecko/20050920 Firefox/1.0.7
195.101.0.67
195.159.130.14 ZoomSpider - wrensoft.com
195.27.247.70 ColdFusion
195.37.209.45
195.39.234.162
195.70.35.179 KummHttp/1.1 (compatible; KummClient; Linux rulez)
196.209.78.70 Mozilla/5.0 (Windows; U; Windows NT 5.1; en-US; rv:1.8) Gecko/20051111 Firefox/1.5
201.230.91.192 Mozilla/4.0 (compatible ; MSIE 6.0; Windows NT 5.1)
201.26.110.67
202.165.102.186 SpiderMan
203.10.224.58
203.113.238.60
203.113.238.60 Random
205.209.169.222 MJ12bot/v1.0.7 (http://majestic12.co.uk/bot.php?+)
206.188.0.11 Jakarta Commons-HttpClient/3.0-rc2
207.148.212.242 PHP/4.1.2
207.171.172.6 Java/1.5.0_04
207.58.161.116
208.185.247.74 PageBitesHyperBot/600 (http://www.pagebites.com/)
209.131.61.1 NutchCVS/0.7 (Nutch; http://lucene.apache.org/nutch/bot.html; nutch-agent@lucene.apache.org)
209.167.50.22 LinkWalker
209.178.137.175
209.18.119.138 Jakarta Commons-HttpClient/3.0-rc2
209.190.20.194 Mozilla/4.0 (compatible ; MSIE 6.0; Windows NT 5.1)
209.237.238.225 ia_archiver
210.17.148.245 Mozilla/4.0 (compatible ; MSIE 6.0; Windows NT 5.1)
210.173.180.156 ichiro/2.0 (http://help.goo.ne.jp/door/crawler.html)
211.5.60.108 RSS_READER (mctwist@mail.dr-k.info)
212.117.84.230 Mozilla/4.0 (compatible; MSIE 6.0; Windows NT 5.1; SV1)
212.117.84.230 Mozilla/5.0 (Windows; U; Windows NT 5.1; de; rv:1.8) Gecko/20051111 Firefox/1.5
212.80.76.5 SeznamBot/1.1 (+http://fulltext.seznam.cz/)
213.133.123.154 libwww-perl/5.65
213.156.54.186 Mozilla/4.5 (compatible; HTTrack 3.0x; Windows 98)
213.176.109.234 Mozilla/4.0 (compatible; MSIE 6.0; Windows NT 5.1; SV1)
213.203.184.30 InetURL/1.0
213.42.2.11
216.195.47.98 Snoopy v1.2
216.22.48.28
216.247.238.226 VSE/1.0 (vivisimolog@web121.com)
217.212.224.142 psbot/0.1 (+http://www.picsearch.com/bot.html)
220.210.177.118 RSS_READER (mctwist@mail.dr-k.info)
221.116.237.114 NutchCVS/0.7.1 (Nutch; http://lucene.apache.org/nutch/bot.html; nutch-agent@lucene.apache.org)
24.11.67.32 Java/1.5.0_06
24.177.134.6 aipbot/1.0 (aipbot; http://www.aipbot.com; aipbot@aipbot.com)
24.19.240.172 Python-urllib/2.1
24.202.166.142 WebPix 1.0 (www.netwu.com)
24.216.179.135 Zeus 34366 Webster Pro V2.9 Win32
24.22.159.131 FyberSpider
24.242.26.149 Mozilla/4.0 (compatible ; MSIE 6.0; Windows NT 5.1)
24.5.187.223 Mozilla/5.0 (Windows; U; Windows NT 5.1; en-US; rv:1.4) Gecko/20030624 Netscape/7.1 (ax)
24.57.8.78 EasyDL/3.04 http://keywen.com/Encyclopedia/Bot
38.113.234.181 voyager/1.0
58.64.126.5
61.135.131.173 sohu agent
62.163.40.65 Java/1.4.1_04
63.229.208.79 NextGenSearchBot 1 (for information visit http://about.zoominfo.com/PublicSite/NextGenSearchBot.asp)
64.127.124.159 OmniExplorer_Bot/5.85a (+http://www.omni-explorer.com) WorldIndexer
64.141.15.119 Wavefire/0.8-dev (Wavefire; http://www.wavefire.com; info@wavefire.com)
64.148.232.129 brfcaofenxv cdvP3k3xuesucrcxgPp3m
64.148.232.129 fWjnyc p ctcwmbbulcdeqw qew
64.164.63.175 Java/1.5.0_06
64.239.7.218 POE-Component-Client-HTTP/0.65 (perl; N; POE; en; rv:0.650000)
64.241.242.18 NutchCVS/0.05 (Nutch; http://www.nutch.org/docs/en/bot.html; nutch-agent@lists.sourceforge.net)
64.38.240.97 Roffle/l.ol(compatible; MSIE 6.0; Windows NT 5.0;
64.40.115.34 Python-urllib/1.16
64.5.245.27 genieBot (http://64.5.245.11/faq/faq.html)
64.94.163.151 Jakarta Commons-HttpClient/3.0
65.19.150.208 OmniExplorer_Bot/5.88 (+http://www.omni-explorer.com) WorldIndexer
65.24.45.49 Mozilla/5.0 (Windows; U; Windows NT 5.1; en-US; rv:1.8) Gecko/20051111 Firefox/1.5
66.117.176.20 Java/1.4.2_04
66.147.154.3 http://www.almaden.ibm.com/cs/crawler [fc14]
66.234.139.194 snap.com beta crawler v0
66.40.35.42 WWW-Mechanize/1.12
67.108.223.130 NextGenSearchBot 1 (for information visit http://about.zoominfo.com/PublicSite/NextGenSearchBot.asp)
68.127.10.143 Mozilla/5.0 (Windows; U; Windows NT 5.1; en-US; rv:1.8) Gecko/20051111 Firefox/1.5
69.0.235.24 Topular/1.0
69.238.36.166
69.41.14.5
70.124.116.68 FavOrg
70.34.224.188 Mozilla/4.0 (compatible ; MSIE 6.0; Windows NT 5.1)
70.49.144.182 Visual_Odyssey_Spider/3.0 (http://www.visualodyssey.com)
70.85.193.178 Poirot
71.102.140.247 envolk[ITS]spider/1.6 (+http://www.envolk.com/envolkspider.html)
71.137.197.195 Mozilla/5.0 (Windows; U; Windows NT 5.1; en-US; rv:1.7.12) Gecko/20050915 Firefox/1.0.7
71.213.9.100 Lynx/2.8.5dev.7 libwww-FM/2.14 SSL-MM/1.4.1 OpenSSL/0.9.6b
80.219.233.222 EmailSiphon
80.255.64.42 SIE-CX70/54 UP.Browser/7.0.2.2.d.3(GUI) MMP/2.0 Profile/MIDP-2.0 Configuration/CLDC-1.1
80.77.86.240 Mozilla/4.0 (compatible; MSIE 6.0; Windows NT 5.1)
81.1.87.163 Mozilla/4.0 (compatible; MSIE 6.0; Windows NT 5.1; SV1; FunWebProducts)
81.155.34.158 Mozilla/4.0 (compatible; MSIE 6.0; Windows NT 5.1; SV1; .NET CLR 1.1.4322)
81.19.66.38 StackRambler/2.0 (MSIE incompatible)
81.73.137.226 Mozilla/4.0 (compatible ; MSIE 6.0; Windows NT 5.1)
81.83.46.233 Googlebot/2.1(+http://www.googlebot.com/bot.html) (Googlebot/2.1(+http://www.googlebot.com/bot.html); MSIE; Windows; SV1)
82.120.57.235 Mozilla/5.0 (Windows; U; Windows NT 5.1; fr; rv:1.8) Gecko/20051111 Firefox/1.5
82.131.195.52 LapozzBot/1.4 (+http://robot.lapozz.com)
83.44.42.199 Mozilla/4.0 (compatible; MSIE 6.0; Windows 98)
84.148.107.62 Mozilla/5.0 (X11; U; Linux i686; en-US; rv:1.4) Larbin/2.6.3 larbin@unspecified.mail
84.148.108.134 Mozilla/5.0 (X11; U; Linux i686; en-US; rv:1.4) Larbin/2.6.3 larbin@unspecified.mail
84.81.17.28 Mozilla/4.0 (compatible; MSIE 6.0; Windows NT 5.0)
85.101.47.187 Microsoft URL Control - 6.00.8169
85.108.164.241 Mozilla/4.0 (compatible; MSIE 6.0; Windows NT 5.0)
85.125.153.160 larbin_2.6.3 larbin2.6.3@unspecified.mail
87.193.34.166 xyz

BTW, this was a slow night!

Wednesday, January 25, 2006

Zoom Zoom SPLAT!

How many fucking spiders and search engines do we need anyhow?

Apparently one more according to Wrensoft, the makers of leeches from downunder.

Obviously someone found another use for ZoomSpider and aimed it at my web site.

Even if they weren't getting in with that spider name the speed they hit my site would've blocked them anyway so Zoom my ass, you got NOTHING!

What's Microsoft doing?

Something hit my server today called SandCrawler and it appears to be coming from Microsoft.

Agent: SandCrawler - Compatibility Testing
Official Name: tide41.microsoft.com
IP address: 131.107.0.84

Anyone know anything more about this one?

Guess it doesn't matter as crawled into a brick wall.

Net Wooing

Another crawler blatantly disregarding my bandwidth and copyright is NetWu with several products to make a webmaster snarl.

My site was hit with this one:
WebPix 1.0 (www.netwu.com)

Must be ethical to write these things as long as you don't worry about the consequences of their use.

The Bus Stops Here

Another Leech 2.0 technology [some call it Web 2.0] called the AnswerBus got a flat tire when it hit my web site. Don't know what question they were asked but the answer was "HELL NO!". They were even nice enough to put a list of other potential wasteful sites that can be blocked as well.

RSS Reader Got Legs

Don't know what it is but something coming from Japan calling itself RSS_READER is trying to crawl but it can't get in.

It's polite too and checks robots.txt then hits the home page WHAMMO! tries again WHAMMO! checks robots.txt again as it's obviously confused then the home page again WHAMMO! WHAMMO! WHAMMO! banging it's head, tries one more round.

Probably someone's lame attempt to locate RSS files, so sad, too bad.

I'm sure it'll be back tomorrow for more fun and games.

Link Bait Manager

Well if you have to have an almost decent excuse to crawl my website all to hell it might as well be under the guise of being a reciprocal LinksManager which at least has some value.

Unfortunately, my web site is a directory with many thousands of pages and after observing their little bot fruitlessly flounder trying to find that reciprocal link it was obvious nothing good was going to come out of this so I blocked it.

If you really want to check links on my site I'd be more than happy to give you an XML API to do so but you'll crawl hundreds or thousands of pages looking for a single link over my dead body.

Buh bye LinksManager.com_bot, buh bye.

FYI, if you want to see a really nice but incomplete [didn't have this one] list of bots check out the database on Robots.org.

Everyone's a Critic

It's not like a I run around the internet spreading filth on other people's forums as they'd boot my ass off except on threadwatch which is a bit liberal when it comes to the four letter words. Besides, it would be just rude to misbehave on other people's websites, or at least I wouldn't do it using a traceable name and IP, I'm not THAT self-destructive. So this is my version of my "Fortress of Solitude" where I can go off on a tangent on anything I damn well please.

Now the critics are coming out in droves [ok, 2 or 3 critics] questioning my content and how I express myself. Let me say that although I do get some sort of perverse pleasure from those types of disapproving comments that's not what this site is all about as I'm not trying to shock anyone, well not too much anyway, ok maybe I try to cause a mild stroke or an occassional headache but really I mean you no harm.

When I initially started this blog I thought I would just do nothing except write clean little helpful technical articles, maybe even slap AdSense on it, and then the evil side raised it's ugly head. I haven't really seen the evil side in a long time since I ran a BBS back in the 80's, drew cartoons, and wrote all sorts of funny as hell but damning things. It crossed my mind to start up a second blog and let the evil side run rampant in it's own little safe haven and not poison the well of my good intentioned technical posts but that never happened.

Maybe it was procrastination or perhaps the need to finally integrate the good with the evil that overcame me and it was time to resolve my split online persona and I said [bet you can guess this one] "FUCK IT!" and the blog went south and never came back.

You have to understand that I'm a guy and I like to do guy things and have guy type conversations but I'm sitting at home working 24/7 with just my wife to discuss things most of the time. She's actually pretty liberal about most topics, way more so than those girly girls and metrosexual men, but there are just times when I cross that line from what she'll tolerate as a conversation and I get the "Save this one for your friends!" quip. That leaves me in a pent up state worse than a teenager in the back seat of a car with a date that won't put out.

Since this is my Fortress of Solitude there will be times that I might just scratch my balls in public and if I happen to offend someone I'm horribly sorry but the political correctness filter has left the building.

You have been warned and thanks for visiting ;)

Exploration Halted

Don't know who these guys are at Omni-Explorer but it always seemed like a legit group that claims to honor robots.txt and posts their IP range so on and so forth. I always let them crawl since they claimed to be venture backed which made me think something useful would show up eventually and being a Silicon Valley guy I'm always curious about venture backed start-ups. However, it's been YEARS now and the bot keeps crawling with no benefit for me that I can see in the near future.

Sorry guys, but your exploration has ended.

OmniExplorer_Bot is now officially arachnida non grata

Taking your Key away

In the blocked crawler du jour contest we call your attention to our latest entry from Canada called the Keyword Encyclopedia.

Load up all your little .htaccess files and drop "EasyDL" in the list of unwanted party guests.

Ta ta bandwidth waster!

V7ndotcom Elursrebmem Suspended in Gravy

Looks like the AdWords team doesn't have a sense of humor and missed the whole point of my most popular nonsense ad running on a nonsense search term.

Your disapproved ad:

Makes It's Own Gravy
Seriously, what kind of ads did
you expect on gibberish searches?
incredibill.blogspot.com
Ad Status: Suspended - Pending Revision
Ad Issue(s): Unclear/Inaccurate Ad Text

Interesting as I thought the satire was pretty clear but perhaps they couldn't get my web site to "Make It's Own Gravy" or maybe they took offense to being called a "gibberish search"?

FWIW, I guess Google really isn't in the AdWords game just to make money as that ad was the top earner racking up 1/3 of all the money I spent on that idiotic ad campaign!

Oh well, one down, 5 to go.

P.S. For you pundits out there I'm still on the fence about whether that whole ad campaign was my way of lampooning the contest or just a desperate cry for attention, you decide.

Yahoo's SpiderMan

Don't think I've ever seen Spiderman crawling before and APNIC claims it's from a registered block from Yahoo in China.

A lookup revealed:
Official Name: d24.search.cnb.yahoo.com
IP address: 202.165.102.186

APNIC claims it's them:
inetnum: 202.165.96.0 - 202.165.111.255
netname: YAHOO-ASIA-2

So now the big question is what's the advantage of letting an all English web site get crawled by a Chinese version of Yahoo?

Anyone have any insights on this?

Tuesday, January 24, 2006

It's a tangled Web we Copy

They call it WebCopier but it should be more appropriately called WebPirate.

The more these so-called products keep showing up the more I realize that the internet is mutating into something very ugly when copyright and bandwidth of the website owners isn't even a concern of the people building these tools.

It's starting to get depressing.

Harvest Gets Crop Failure

Caught Topular's hand in the cookie jar today.

69.0.235.24 - - [24/Jan/2006] "GET /myarticlesarenotyourarticles.html HTTP/1.1" 200 1302 "-" "Topular/1.0"

According to their website they do "Information Harvesting" without permission of course and no information posted about their robot or any other damn thing, but since it didn't check robots.txt there's no chance it's playing by the rules anyway.

Guess what Topular, your days of harvesting my shit are over.


Picture THIS!

We have yet another new bandwidth leech called PicSearch sucking the lifeblood of the internet coming to us from Sweden.

That's right boys and girls, add "psbot" to your blocked list.

I'm thinking about actually letting them index just one picture of me flipping them the bird with a caption "Pay my bandwidth fees you fuckheads".

Tools for Fools

Here's one to file in the KISS MY ASS column: Website Extractor

You may want to block anything with this user agent:
"Website Quester - www.asona.org"

Product claims to have the following benefit:
Website eXtractor saves you time and effort by downloading entire Internet sites (or the sections you stipulate) to your hard drive.
Let me help with this as I saved your customer even more time and effort as their sorry ass was blocked from downloading a single fucking page.

Assholes.


Not So Fav Icon

OK, when I pull a major blunder I do it right as minor fuck-ups are for amateurs.

Follow along carefully as this will all make complete senselessness eventually...

This problem all started sometime recently as it appears somewhere along the line my favicon.ico got zapped off my server and I never noticed nor did I bother looking at the logs close enough or I would've figured this out a few months ago.

Now imagine that my Apache configuration doesn't know the favicon.ico is an image and on a 404 error was actually displaying a 404 page for the missing icon.

Next, trying to capture more visitors instead of letting them see a 404 page and leave, possibly because of site maintenance errors, the 404 page at some point was redirected to my home page.

Last but not least, I changed my mind a few days ago and put my bot stopper code on the home page after seeing what scrapers could do with just that little amount of content.

Suddenly a small rash of people got banned with about 30 page views in 5 seconds. Looked at what was happening and these people hadn't downloaded 30 page views but had a shitload of requests to favicon.ico which looked very odd. Must be getting dense as it took a couple of days of seeing this before my little brain said "note the favicon.ico requests getting a 404 error".

Let's see what's going on here and try it:
http://www.youdumbasshole.com/favicon.ico

Up pops the home page!

Oh fuck.

So a browser or something asking for the favicon.ico about 20 times in a row loaded 20 404 pages which redirected to 20 home pages which tripped the scraper alarm and stopped them from accessing more pages temporarily.

Oooops!

Uploads favicon.ico, tucks tail between legs, hides quietly in the closet until the massive wave of embarassment passes.

Tales From the Crapped

If you're squeamish about bathroom situations, close your eyes while you read this.

So I'm sitting in the recliner and suddenly get a sharp pain in my side that feels like something large just outstreched vertically in my intestines so I stretched out in the recliner to try to relieve the pain, then it suddenly shifted horizontal causing me to spasm in the other direction. Feeling much like there's something playing X-games in my intestines this happens a few times from left to right, quite reminiscent of atomic diahrea that accompanies the stomach flu.

Great, just what I need to be getting sick.

If I were gay I would've thought it was the baby kicking but I digress.

Now comes the moment of truth, I don't know if I have to fart or shit, never a good sign.

Then without warning or fanfare comes the sudden emergence of the turtle head and the mad dash to the bathroom.

This was no ordinary trip to the bathroom, I had to get a LaMaze coach to help me with my breathing "Now PUSH!" ... "UHHHN"... "PUSH!" so I can only imagine this is somewhat similar to child birth as it feels like I have just opened up so large I could suddenly slide over the toilet bowl.

When the accompanying paperwork is done is when this traumatic trip to the bathroom reaches epic proportions.... never in my life have I seen such a thing, it's a mutant, it's HUGE! it's ENORMOUS! It's the Empire Shit Building standing entirely up the side of the bowl laughing at me as I stare at this forearm sized dung heap in horror.

What the hell did I eat?

Now the moment of truth, time to flush.

[cue theme from Jaws: bum bum bum bum bum bum...]

The water goes up, up, up, up and over the top while this big clinker just sits there mocking me without budging. [digression: Water water everywhere and not a drop to drink] I'm quickly deploying any handy towels as fast as possible so this turdnami doesn't make it to the carpet.

Anyway, you get the idea, a lot of urping and plunging came next.

I need to change my diet as that's some crazy shit that I don't need.

Monday, January 23, 2006

Pressure to Perform

Now I'm starting to get nervous as the pressure is on now that we're up to 5 whole readers and people actually think this blog is funny when it started out semi-serious. My wife is accusing me of using gratuitous cursing just to pander to my main audience (you both know who you are) and claims the blog will end up sillier than Scrubs or worse yet when NBC cancels me like they did Will & Grace.

Not to mention Sebastian is claiming I have tits and suddenly people looking for tranny porn are landing here via MSN which is probably a step up from the usual horse sex crowd. [side note: most of the horse sex requests are coming from the Middle East, camels aren't in vogue anymore?]

Then someone shockingly saw right thru my facade:

When reading his blog one word and one word only comes to mind, curmudgeon.
My wife understands that comment as my online game playing persona is CrankyBaztard which she claims was no accident that I picked it as my name since it was a such a natural fit.

So now I'm all nervous, to curse has become a curse, to not curse is worse.

Ah fuck it.

TIP: Asking your wife if you can "Play Moses and part the Red Sea" once a month does not work.

Too Stupid to Scrape

This one should be filed under "Oh My God What a Moron" as someone slammed my server today attempting to download my content with a minor twist - they got the case on all the page names wrong!

All of my pages use Upper/Lower case file names like Page1_Blah.html

Look at this shit:


0.0.0.0 - - [23/Jan/2006:14:14:48 -0600] "HEAD /page1_blah.html HTTP/1.1" 404 - "-" "-"
0.0.0.0 - - [23/Jan/2006:14:14:48 -0600] "GET /page1_blah.html HTTP/1.1" 404 1302 "-" "-"
0.0.0.0 - - [23/Jan/2006:14:14:53 -0600] "HEAD /page2_blah.html HTTP/1.1" 404 - "-" "-"
0.0.0.0 - - [23/Jan/2006:14:14:54 -0600] "GET /page2_blah.html HTTP/1.1" 404 1302 "-" "-"

The page names were all correct but lower case which sure as hell won't work on a Linux server!

Never thought I'd see a scraper too stupid to scrape!

That's one dumb asshole.

Poor Kitty, Too Funny

Just about hurt myself ROTFLMAO when I saw this entry in my webstats as some poor distressed pet owner searched MSN for "if cat barfs is there something wrong" and landed on Cat Tales of Horror as the #1 result.

Tears are still running down my face, that poor person, I almost feel bad for them.

Ya know what?

Fuck it.

They should get a dog if cat barf worries them so easily as they'll soon not have a single spot anywhere in the house that isn't somewhat slightly stained by brightly colored cat vomit.

TIP: When decorating color coordinate with your brand of dry cat food.

Bot Busting Could Have Significant Savings

The total reduction of 10's of gigabytes of bandwidth on my server alone due to bot stopping makes it easy to imagine that having such bot busting technology installed on every server in a datacenter could be an enormous savings in bandwidth second only to stopping spam. This technology could result in a small windfall for small hosting companies constantly being squeezed by service providers for more money by allowing even more customers on the same bandwidth currently being stolen without permission. Conceptually, blocking these leeches from an entire network could result in all sorts of additional savings.

The need to upgrade motherboards, especially for busy shared servers, could be significantly lessened. The older motherboards currently straining under the load, similar to how my newer dual Xeon was, would suddenly be more than adequate to continue to grow a business without any additional equipment expenditure. Being able to get a little more juice out of older equipment could allow datacenters to spend more on infrastructure instead of further lining the pockets of service providers.

Now the problem is how do you sell a product to hosting companies that could actually impact their revenues by cutting bandwidth usage which results in additional charges?

Simple.

Offer the bot busting technology as an additional paid service labelled as a content and copyright control technology that reduces the ability of scrapers and aggregators from using their content without permission.

Seems like a natural for a control panel plug-in for Plesk, CPanel, etc.

More revelations coming soon.

I'll show you PRIVACY...

Another useless excuse for a website called PrivacyFinder crawls a few of your pages looking for your p3p privacy policy and combines that oh-so-useful information with Google and Yahoo search results.

They just got a taste of MY privacy policy today as their bot couldn't get past my front door.

If this little bit of information was useful to include in the SERPs and customers demanded to see it then Yahoo and Google could just include it in the first place.

Go find your privacy elsewhere and keep your ass off my server.

Stupid.

Link Your Ass to My Foot!

More link exchange bullshit as this excerpt was one of the best lately:

Dear Dipshit,

We are pleased to inform you that your website http://www.youreanawesomewebgod.com has been listed in our site http://www.stupidfuckingpondscum.org

You can find your link at: http://www.whogivesaflyingfuck.org/index.php

Links exchange means that you need to put reciprocal link to us.

Preferrable on this page http://www.notonmywebsitenotonyourlife.com

Our robot have checked this page for 5 times but our link wasn't found.

Threats about not linking to us and losing your link blah blah I think I shit my pants etc.
Guess what?

Your robot can use that phillips head screwdriver attachment and thoroughly fuck itself.

What kind of morons are harassing me with this nonsense?

I'll link to your web site about the same time I become a rock star and my balls start slapping Pamela Anderson's ass after a concert which is NEVER!!!

Now go away, eat shit and die, leave me alone.

Sunday, January 22, 2006

Block this Server Side Browser

Here's a real winner that must have a page of links somewhere that spiders crawl via their proxy server as it was looking like an attempted page hijacking in Google when it was discovered.

These slimeballs download your site via the proxy server, strip your javascript so the frame busters don't work, and slaps their ads for pecker pills on the top of the page.

Ran into a similar site from China last year but they were embedding AdSense into the page and Google took care of them in short order.

Currently you can block them both via IP and the referrer as their proxy isn't terribly clever yet and leaves their domain name in the referrer string.

Some SEOs are as DUMB as Pet Rocks

Which is an insult to Pet Rocks.

Some of you know that one of my main websites is a niche directory that has been online since before the DOT COM boom and Yahoo was still mostly used as an adjective describing people living in the south.

Anyway, some genius SEO/Web Designer/Pinhead submitted a listing for a client to my directory today and did the following:

  • Put a bunch of keywords in the title, yes, nothing but keywords
  • Put a bunch of keywords in the description, if you can call it that
  • Put in HIS email address wrong with his company name butchered all to hell
  • Pissed me off
I swear to god my cat can hack up hairballs with higher IQs!

Come on, it's a DIRECTORY, not a SEARCH ENGINE so pull your SEO head out of your ass and act accordingly!

Is the word TITLE too complicated?

Is a simple DESCRIPTION of what's provided at the website mind blowing?

Couldn't you just cut and paste your email address without me having to mop up after you?

Showing that my IQ is above room temperature, unlike that SEO, I was able to figure out who this guy was in 2 seconds by pasting the butchered domain name on the email address into Google which ran it's "people are stupid filter" and it figured out what it was supposed to be and landed me right on the guys web site.

Quick check with WHOIS.SC popped up the same name as owning that domain that submitted the site and the IP address was geographically similar enough that I was sure it was the same person.

How do people get work for themselves when they can't even get their own email address right?

More importantly, who in the hell even types in an email address anymore with all these auto-form filling tools built right into the browser?

What a dweeb-assed shithead, I need a drink...

Copyright Crawlers? Get the gun!

The boatload of irrational 404 errors showing up in my web stats suddenly makes a lot of sense as my spider trap snared some asshole today bombarding my server with a shitload of requests for pages that don't exist.

Well guess what?

It appears the crawler was looking for any stolen copyrighted pages and abusing my server in the process.

Who gives these copyright protection services and tools the right to fucking attack my server requesting 100s of pages a minute and suck up my bandwidth dumping 404 pages?

Now that you can't scan my site maybe I'll just locate some of the pages you were trying to find, steal the damn things, and put a big FUCK YOU on the top of each of those pages.

Not like you'll ever see it but everyone else can laugh their asses off.

Fuckers.

Saturday, January 21, 2006

We Want Your Ad Space

The next deluge of emails after the link swapping morons are those greedy little make believe media companies that want my ad space.

Must get 10-20 of these a week and they all want to sell my link space.

Let's examine the potential here as they claim they'll only take 25% or 50% to "sell my space" depending on which bullshit artist company sends the email.

If they really looked at my site they would notice I also sell ads direct and take 100% of the revenue plus some AdSense which is about 60%.

So do they really think they can compete with my direct sales plus Google AdSense?

Both pay many thousands a month already and both are pretty reliable as far as getting paid, especially my direct ad sales, so what's in it for me?

On the rare occassion that I've had these types on the phone I ask two questions:

  1. Do you have significant ads in my industry or 100% targetting to my topic?
  2. Can you guarantee that you can replace my ad income at my current levels with your advertisers?
So far the answer has always been NO on both counts so why do they persist?

Idiots.

Hi! I'm Looking for Link Partners!

Those emails always start the same with minor variations:

My name is BLAH.
I work for http://www.blah.com/
I am looking for link partners whose sites would be of benefit to our visitors.
Your site would be an excellent fit.
Sorry pal, but you obviously didn't visit my site.

My site is about WIDGETS and not web hosting, pills to make your pecker hard, weight loss, real estate or any other damn bullshit you're selling.

You know what would be an excellent fit?

My foot up your ass.

Now go away boy, you're bothering me.

Scraping Down, Ad Revenue Up!

Somewhere in the past I rambled about my revenues getting stomped when greedy crawlers and thieving high speed scrapers hammered the crap out of my servers locking out legitimate visitors for minutes or hours during what could be considered a DOS attack based on the speed of requesting 40K pages.

Well here's a big shock, now that I've effectively stopped their asses cold my ad revenues have returned to levels they were about 3 months ago before the crawling became a near epidemic.

Makes you wonder if some of my listings were suffering in the Big 3 search engines because of this as my review of several log files showed that sometimes all 3 search engines were attempting to crawl at the same time some of the big time scrapers were tying up my server. That's when I suspected the Big 3 SEs timed out on those pages and lowered the listings in the SERPs like it did when I recently caused a problem and they've taken this long to get back where they were.

You know it was getting real bad when one night I get a wake-up call at 2am by my sister-in-law, who has sites on my server, calling to complain it went down 20 minutes ago while she was working on her web site and slightly afraid she did it. Pings to the server and various services confirmed it was up and running but unable to respond to data requests as it was just tied up, completely overloaded, and wouldn't even give me a prompt in SSH so I could kill the tasks and block the intruder. However, on that night I let it ride as I hate forced reboots that can crash a database (no sleep then) and sure enough it came back to normal an hour later as I expected.

Anyway, just thought someone that's been reading this saga might find this interesting as I certainly don't think it's a coincidence the ad revenue is bouncing back at the same time the crawlers have been beaten to a pulp.

Friday, January 20, 2006

PageBites Job/Resume Scraper

Well guess who stepped into my spider trap today but yet another robot from yet another start-up aggregator site called PageBites that thinks they have entitlement to make money sucking my bandwidth.

Like I've been telling you all for a long time now you need to raise your sheilds to OPT-OUT your site to all crawlers and whitelist just the ones you want to stop this pandemic crawling of your sites. They profit off your backs, gobble up bandwidth costing more money, then muck up your web stats to the point you can't tell your advertisers how many real impressions they really get as crawlers are becoming a pretty decent percentage of so-called visitors on a daily basis.

Search engine spam, email spam, blog spam, now crawler spam.

It's really starting to get to the point that I think turning my spider trap into a product so everyone can take control of their own sites is looking more viable by the day.

You can all take your robots and go home, party over, your ass never got past the home page.

Firefox Scraping Giggle of the Day

Just had an amusing scrape attempt from something that claims to be Firefox with HTTP_REFERER set properly as it crawled and everything but it attempted to rip 299 pages in 211 seconds which set off the alarms instantly and automatically shut them down after only a fraction of the page requests at that speed.

Maybe there's a Firefox plugin that did this and if that's the case it's just getting Firefox users blocked but I don't care as this kind of behavior isn't welcome.

Mozilla/5.0 (Windows; U; Windows NT 5.1; en-US; xxxx) Gecko/xxxxx Firefox/1.0.7
I was amused watching it happen in real time but you lamo scrapers didn't really think it would work did you?

What my scraper blocker used to do was just stop counting page requests after it hit a specific threshold and temporarily disabled the scraper to stop them. However, my latest modification keeps counting continued attempts so after the initial threshold trigger blocks them the page counter just keeps going to see how many pages they really wanted. Eventually the scraper will set off a second level threshold trigger that gives them a permanent ban automatically if the total page requests are too extreme.

Pretty obvious when it just keeps going that there's no human at the controls.

Too funny - got anything better to throw at me?

Boycott Bellsouth

Everyone is going on and on about the Bellsouth drama where the good old boys at BellSouth are trying to charge (blackmail) internet companies a premium for using Bellsouth's backbone.

You can all pontificate about these blowhards at BellSouth all you want but my strategy is more straightforward.

Put your money where your mouth is.

Get rid of DSL and switch to a cable modem, satellite or anything except DSL.

Toss your landline phone in the trash and use VoIP, cell or anything else as long as it isn't BellSouth.

We aren't in BellSouth territory, we're in PacBell country, but we were also sick of all their overpriced services so we virtually freed ourselves of all RBOC services except a bare-bones $25/month landline mostly for incoming calls and emergency backup for internet dialup for those rare times when the cable modem goes offline.

Besides, we have a better phone service package with our cell phone so they can take all their overpriced features and go pound sand.

Basically, if people bail from BellSouth in masses they will get the message loud and clear when those year end multi-million dollar corporate bonus packages the execs are fond of go down the crapper.

This isn't the 80's anymore and pretending to be a monopoly when you really aren't is just stupid.

Thursday, January 19, 2006

So Many Rants, So Little Time

Yesterday I was all riled on up on a bazillion topics and instead of ranting all day decided "Fuck It!" and worked on my websites instead - not like you fuckers pay the bills.

Brief synopsis:

Gov't wants Google Searches:
They just want to know what we're searching for, not who's doing it, but as I see it as the government is stepping over their boundaries and Google is vying for martyrdom by turning them down. Sorry, but I don't see the church annointing St. Google anytime soon so if it doesn't contain personal information like IPs and such just turn it over Google you link baiting media hounds.

GoDaddy Shuts Down Websites:
Any moron that hosts with GoDaddy and can't abide by the terms of service gets what they fucking deserve so stop whining already, it's getting old.

German Judge Shuts Down Wikipedia.de:
Parents didn't want their son's name in the Wikipedia so they sue and now it's in 10,000 blogs instead just because some Oktoberfest liver transplant candidate masquerading as a German Judge doesn't know shit about the internet - PRICELESS

Last But Not Least:
Don't expect to get laid the rest of the week when your wife overhears you washing your hands at the sink muttering comments about "pussy fingers"

Until tomorrow...

Scrapers Don't Like Being Blocked

The last week has been getting more interesting as my banned scraper log file shows some rather interesting trends as they are squirming and thrashing trying to get around all the traps.

The most amusing is the ever changing user agent strings as they are definitely testing to see if I'm filtering based on specific user agent criteria and mostly they are right as everything is banned except http clients.

All of the legitimate search engines are being permitted based on their range of whitelisted IPs so trying to pretend to be Google, Teoma, Slurp, etc. will just instantly ban their IP for the day and repeated attempts might ban it permanently.

Almost as much fun as shooting fish in a barrel.

Wednesday, January 18, 2006

Courts Give Wendy's Chili Hoaxers the Finger

Sometimes you have to wonder about jurors as it's OK to kill your wife if you're O.J. or molest children if you're M.J., but mess with Wendy's Chili and your ass goes to jail for 9 years.

Guess people have their priorities.

Competitor Jumped the Shark

Nothing makes your morning like waking up to find an email from your competitors latest mass mailing explaining how he's working on his web site and all these improvements and fear sinks into your gut that you're about to be destroyed by something awesome.

You click the link with dread expecting to see COMPETITION 2.0 and as luck would have it you see HILARIOUS 2.0 instead.

I swear on a stack of religious mumbo jumbo that this guy used to have a site I considered a threat and now it looks more like some high school kid is doing his web design and things are broken all over the place.

Either he's thrashing trying to get some juice out of his site or he's lost his mind and it's about to go down in flames but either way it looks like a win-win for me based on what I'm seeing.

Google Analytics Accuracy Bullshit Challenge

Have you played with Google Analytics?

Has the happy horseshit syndrome settled in yet?

My web site shows the following stats:

1 direct access
2 http://domain1.com
3 http://www.google.com/search
4 http://domain2.com
5 http://search.yahoo.com/search
6 http://domain3.com
7 http://domain4.com
8 http://domain5.com
9 http://domain6.com
10 http://domain7.com
However, Google Analytics shows:
1 google
2 yahoo
3 (direct)
4 msn
5 aol
6 http://ga-domain1.com
7 http://ga-domain2.com
8 ask
9 aolsearch.aol.com
10 search
Best I can determine is Google combines all Google sources such as Google.com, Google.ca, Google.co.uk, etc. which makes it look more dominant as a single source but overall makes the actual weight of the individual Google sites merged into one big ass murky pile of BULLSHIT!

Worse yet is from my actual log files my #1 domain referrer shows as #62 in analytics.

Sorry Google, you can fool some of the people some of the time, and AdWords advertisers most of the time, but here at IncrediBILL's Random Rants we call this BULLSHIT!

Have a nice day.

Tuesday, January 17, 2006

Bot Busting Crawler Experiment Complete

Many weeks and log file combings after The Great Anti-Scrape Off started it's become quite obvious that the effort was an enormous success.

The last bit of technology was deployed a couple of nights ago to challenge robots masking as humans seems to be stopping the last of them so it would appear that my site is now reasonably safe from typical crawlers and bots.

If someone has access to 10,000 IP addresses all bets are off but most scraping and crawling operations, except those that appear to be hiding behind AOL, seem to have fairly limited resources.

The last couple of tricks deployed include:

  • Multiple checkpoint profiling to identify bots masquerading as humans
  • Randomized challenge techniques with anti-blow-thru detection so that the typical captcha defeating techniques won't work
  • Adaptive time monitoring for hit and run bots that seem to think they can get small chunks at a time and come back later under the radar for the next chunk
There may be other things going on out there in the wonderful world of scraping but it would take a fairly sophisticated scraper to bust through what's now currently in place.

The technology seems to work fine so far with up to 30K page views a day but it would be interesting to see how it would perform with 100K or 1M page views a day. What might be a bit challenging is the current implementation does quite a bit of database churn but for a medium-sized sampling that's only tracking a few hundred visitors at any time which is fairly insignificant.

In the end my scraper stopper is only protecting my database of content so any crawler can access about 10 pages without question such as the home page, about us, contact us, etc. so it will be painfully obvious to them that they are being blocked from delving deeper into the site.

The benefit to this approach is that all of the hard rules being used to block access to the full content doesn't break access to other technologies like the RSS feed which appears to have all sorts of crappy homegrown readers that don't identify themselves. However, when the greedy homegrown readers try to behave like a crawler and step into the site to grab the content linked from the RSS feed they are blocked unless expressly whitelisted.

The additional benefit to allowing a handful of top level pages to be crawled is that the web site doesn't automatically drop out view of lesser search engines or up and coming technology which would happen with a more harsh approach using the .htaccess file blocking all access to any pages. Additionally, there is a nice message on every blocked page letting them know they're probably seeing that page because they are an unauthorized crawler and legitimate crawlers may contact the webmaster and petition for access.

Basically, my web site has become OPT-OUT to any aggregators, crawlers or scraping thieves and now they will need to ask for permission to be let inside and profit from my work. Assuming it's a mutually beneficial proposition then I'm sure I'll let them crawl the site.

Now comes the million dollar question of whether to convert this to PHP and attempt to find a market or just keep it under wraps and much less conspicuous so the scrapers can't study what I've done and find any loopholes in the technology to exploit.

One final thought:

Could you imagine an entire internet that is OPT-OUT from crawlers?

The ability for the next Google to crawl the web to prove their technology would be a severe challenge!

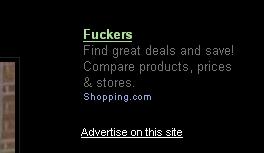
Local Radio is Dead

Now that I've had a Sirius Satellite Radio for a couple of weeks I'm hooked.

Normally when I'm driving around in the car I'm sitting there punching one button after another looking for music in a sea of commercials or looking for some talk radio worth a shit and find nothing. Prior to Sirius my little Zen Micro had become my default music player in the car so at least I could listen to something I wanted to hear and pay attention to my driving instead of the non-stop button pushing.

Heck, now I'm listening to more radio than I have in many years as we just got the home docking station so it's Sirius in the car, home and office, it's on a LOT.

Thanks to Howard taking us kicking and screaming into a subsciption radio service as I'd SIRIUS-ly be missing out on the radio revolution if I hadn't made this switch.

Monday, January 16, 2006

Scraping From AOL Users Possibly Confirmed

There has been past speculation that someone is hiding behind AOL's proxy servers doing scraping and tonight I just happened to catch it live and decided to try something.

The pages were downloading at a slow clip via AOL with a user agent like this:

Mozilla/4.0 (compatible; MSIE 6.0; AOL 9.0; Windows NT 5.1; SV1; .NET CLR)
The minute I blocked them they tried about 10 more URIs with that user agent string and it suddenly changed to:
Mozilla/4.0 (compatible; MSIE 6.0; Windows NT 5.1; SV1; .NET CLR ; .NET CLR ; Something I removed)
To me this proves there is someone cloaking under the bank of rotating AOL IP addresses and they just happened to download enough to catch my attention this time and tried a non-AOL browser once I stopped them.

Time to implement a little more sophistication in my bot blocker.

Sorry slick, you aren't.

BUSTED!

Cursing at Scrapers

Just for giggles I went looking to see what idiots were scraping and reposting my random rants and sure enough I found some asshole with a snippet of one of my rants in some made-for-adsense aggregator site and sure enough that page was running PSAs.

Listen up fuckwads, if you're gonna steal my shit then you better filter it to make it "family safe" for AdSense.

Fucking morons.

V7ndotcom Elursrebmem Punted by Google

Doing a few repetitive searches on Google just to see what ads were showing up resulted in this every now and then:

Your search - v7ndotcom elursrebmem - did not match any documents.
Does that mean some servers aren't updated yet with this SEO contest?

Not sure why people are having a contest to get to the top of a defective search engine.

Pay Per Crawl

With the web 2.0 aggregator craze at an all time high maybe it's time for a new business model of Pay-Per-Crawl. That's right, all the start-up leech sites wanting to waste our bandwidth should be sharing some of their VC loot with us just for the privilege.

I'm not talking about ripping anyone a new ass, but perhaps $5 per every thousand pages crawled would help cover my costs of dedicated servers and bandwidth.

Heck, if it wasn't for all the crawlers in the first place my prime site wouldn't even need a dual Xeon server to handle the load so all the bots are definitely running up my expenses so why in the hell shouldn't they share some of that cost?

Oops, they are sharing some of the cost now as I locked them all out so they can't profit from my hard work.

Too bad, so sad.

I'll take a check, money order, VISA or MASTERCARD to let your crawler back in but don't you dare ignore the crawl delay or anything else in my robots.txt or back out you go!

Who's Yer Daddy?

Did anyone notice advertising on the V7ndotcom Elursrebmem SEO contest?

So just to be a me-too I put up one serious ad:

Publishers Earn More
Free report on maximizing your ad
revenue - nothing to purchase
incredibill.blogspot.com

Then I put up one to make them go HUH?

Cat Tales of Horror
Cuddly Pets Terrorize Owners
Laugh, Cry, Run for your Lives
incredibill.blogspot.com
What possesses me to do this shit?

I'm old enough to know better, but spending my own money just to make people go "what the fuck is wrong with him?" may be a little over the top even for me ;)

v7ndotcom Elursrebmem Battle of Yahoo vs MSN

Yahoo leads the pack claiming about 151 results for V7ndotcom Elursrebmem

MSN in a close second returns117 results containing V7ndotcom Elursrebmem

With sad ass Google returning only 10 results for V7ndotcom Elursrebmem

This is nothing new as I've been reporting Yahoo and MSN regularly tear Google a new ass when it comes to new content ever since I started this blog and Google is still in slow motion. Google is behaving more and more like your slightly slower older cousin with a learning disability.

Blank User Agents

Who in the hell is using blank user agents on the web?

I can't tell if these are SpamBots, Scrapers, Trackback Pings, all of the above but none of them are getting thru so it doesn't matter.

They must naively think if people block per user agent string that if you have no user agent string you'll slip thru the cracks which might've been true until my paradigm shift switched from blacklisting to whitelisting.

You people still blacklisting, and you know who you are, are wasting your time on a no-win scenario that just doesn't work.

Sunday, January 15, 2006

V7ndotcom Elursrebmem

The great race to win the SEO contest for "V7ndotcom Elursrebmem" is on and it's actually surprising to see results so early in the contest.

SEO's get your V7ndotcom Elursrebmem's in early and often and may the best V7ndotcom Elursrebmem placement win!

Yes, this is a lame attempt at V7ndotcom Elursrebmem stuffing.

Blocking Reveals Odd Traffic Hits

Now that I've tightened the noose even tighter on bots and user agents there are some really odd hits showing up in my auto-blocked log file when analyzed for any false positives.

Something very odd has surfaced with a lot of single page requests coming from seemingly random IPs with no identification whatsoever, just the page request, but doing a reverse DNS lookup can be very revealing.

One such revelation was something I've never heard of called Covenant Eye's with an anonymous spider hitting my site. Since Covenant Eyes is a paid service it's too bad since they aren't going to be collecting any more free informaion by scanning my site. If you people figure out I'm blocking you and you really want access bad, maybe we can work out some financial terms for accessing my site!